Why IT/OT convergence stalls at integration, and how to get it moving
Key Highlights
- Context matters more than connectivity. Moving data from point A to point B isn't convergence. Uncontextualized data feeding automated decisions is a risk, not an asset.
- Start with the use case, not the infrastructure. Projects that begin with the business need and let it set infrastructure requirements avoid "pilot purgatory." Narrow, scaled deployments are where ROI comes from.
- Lifecycle mismatch is structural. IT refreshes infrastructure every three to five years. OT expects equipment to run for 20. Governance must bridge that gap.
- Multi-vendor is the norm, and often the preference. 73% of sites run four or more vendors, and 49% of respondents prefer multi-vendor environments, so interoperability is the top need (37%).
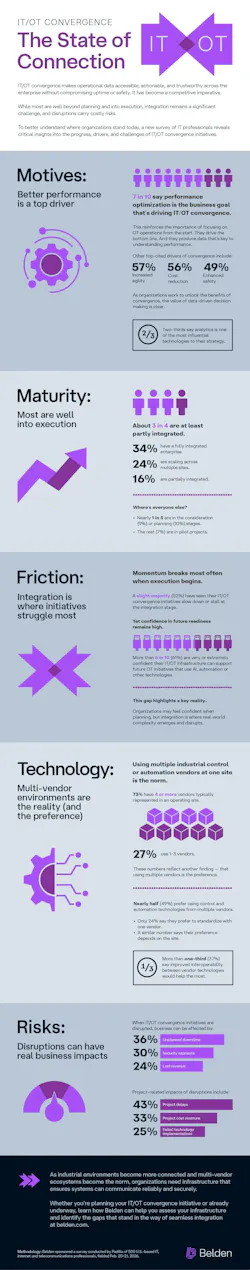
IT/OT convergence has moved from boardroom concept to plant-floor reality. A Belden-sponsored survey of 500 U.S.-based IT, internet and telecommunications professionals, conducted by Padilla finds that about three in four organizations are at least partly integrated: 34% are fully integrated across the enterprise, 24% are scaling across multiple sites and 16% are partially integrated. Seven in 10 say performance optimization is the business goal driving the effort.
The data shows a gap. More than six in 10 respondents (61%) are very or extremely confident their infrastructure can support future AI and automation initiatives, but 52% have watched convergence projects slow or stall at the integration stage. The consequences are tangible. Respondents cited project delays (43%), cost overruns (33%) and failed technology implementations (25%), as well as unplanned downtime (36%), security exposure (30%) and lost revenue (24%).
The full results are laid out in Belden's infographic, "IT/OT Convergence: The State of Connection," which covers motives, maturity, friction, technology and risks.
To help control engineers read the numbers from the plant floor, we spoke with Ashwani Singh, senior director of global R&D operations at Belden. Singh works at the intersection of connectivity infrastructure, industrial networking and emerging AI-driven tools. He explains why the survey's IT-side optimism doesn't always match OT reality, and what practitioners can do about it.
Q: What's the one thing about IT/OT convergence that people consistently underestimate?
A: It's that old phrase: "water, water everywhere, and not a drop to drink." In our world, it's data, data everywhere, and no actual information. Most companies today are data-rich but information-poor. People think IT/OT convergence is just plumbing, putting in a pipe to move data from point A to point B. What they underestimate is what it takes to make operational data accessible, actionable and trustworthy across the enterprise without compromising uptime or safety, and the absolute need for context. In the old days, we said, "garbage in, garbage out." In the world of AI and convergence, it's "garbage in, poison out," because bad or uncontextualized data leads directly to bad automated decisions.
The other thing people underestimate is the human side, what I call internal digital diplomacy. You're merging two completely different worlds where a governance model simply isn't there yet. You also must realize where your edge is. A customer once asked a very valid question: is the edge at the OT level, or is it at the databases where you contextualize data? For me, you create your edge where you need it, not just where a diagram says it should go.
Q: 61% are very or extremely confident that their infrastructure can support future AI and automation, yet 52% have seen projects slow or stall at integration. How can both be true?
A: There's a massive gap between the theory of network capacity and the reality of the plant floor. The survey shows that about three in four organizations are at least partly integrated, so they feel very confident about their backbone infrastructure during planning.
But the 52% who see projects slow or stall run into real-world complexity at the exact moment they try to integrate across the Purdue model, which fundamentally hasn't changed its core since the '80s. Manufacturers often start with an "infrastructure-first" mindset rather than identifying the business need, defining the use case and letting that use case drive the infrastructure requirements. They also hit a wall with brownfield versus greenfield, where the rules of engagement are completely different. You have trillions of dollars of existing Industry 3.0 infrastructure that now has to work in a 4.0 world. And companies get stuck in "pilot purgatory," running wide, unfocused pilots when true ROI only comes from narrow, scaled deployments.
Q: Why does confidence stay high even after stalls? Is it optimism, or a blind spot?
A: It's less a deliberate blind spot and more a natural difference in perspective, a classic forest-versus-trees scenario. Looking at convergence from the top down, there's a lot of optimism that standard Ethernet or wireless technologies will seamlessly bridge the gap. This survey polled 500 IT and telecom professionals, so it naturally reflects that vantage point: if the network is up and data is moving reliably, the foundation looks successful.
The challenge is in the metrics used to measure success. Standard IT KPIs translate well to management dashboards, but they don't always capture the physical realities of the plant floor. That can mask integration challenges and the specialized skills required to bridge the two worlds. There's often an expectation that deploying AI or new software is a purely digital rollout, but the physical complexity of the factory floor reveals itself once organizations move past pilots and try to scale in a real-world environment.
Q: Since respondents were IT professionals, how might OT and control engineers read these results?
A: Control engineers naturally view these numbers through the lens of the physical plant. When IT professionals express high readiness, OT engineers tend to see it as long-term optimism rather than immediate reality. It's like expectations around innovations like APL or Single Pair Ethernet. They offer great potential, but they won't replace existing network infrastructure and equipment overnight.
From the factory floor, we consistently hear that applying standard enterprise IT approaches directly to redundant control systems doesn't always translate cleanly. In many cases, replicating IT architectures in an OT environment can require more hardware, increase costs and introduce new potential points of failure on the line. Control engineers prioritize absolute reliability, which is why proven fieldbuses like CAN, Profibus and AS-i remain critical and aren't disappearing anytime soon. Even a promising technology like SPE, with great features like multi-drop, is part of an evolution rather than a sudden switch.
Ultimately, OT engineers know it's not an either/or choice between old and new. That's especially true given that 73% of operating sites manage four or more vendors, and 49% of respondents prefer multi-vendor environments. As hardware and connectivity layers continue to merge, with switching integrated directly into devices, the priority shifts to making these diverse ecosystems work together smoothly. That's why 37% of respondents pointed to improved interoperability as their biggest need. Success requires co-designing these architectures collaboratively, blending IT's enterprise vision with OT's physical realities, rather than relying on a top-down mandate.
Q: Does that 61% confidence figure match what you see on the plant floor?
A: That confidence makes perfect sense for a brand-new greenfield site. But most plant floors are complex, established brownfield environments managing four or more different vendors. Ensuring these diverse ecosystems communicate reliably and securely is a heavy lift, and it requires treating the infrastructure as an active, continually managed environment rather than a "set it and forget it" installation.
There's also a fascinating workforce transition happening. While much of the conversation focuses on AI replacing roles, the more pressing challenge is bridging the operational skills gap. Much of the incoming workforce brings strong digital skills and is intuitive with digital interfaces, but they naturally lack the decades of hands-on OT knowledge that experienced employees have.
Because of this, a robust network backbone is only part of the equation. What teams on the floor need to feel confident are practical playbooks, operational procedures and reference guides from experienced veterans, along with tangible deployment examples. That ground-level enablement is what turns IT infrastructure confidence into real operational success.
Q: What specifically goes wrong when execution begins? Is it protocols, legacy equipment, network architecture or organizational issues?
A: Honestly, it's a collision of all of them, and it has real project impacts: 43% of projects get delayed, 33% see cost overruns and 25% face failed technology implementations. It starts with organizational issues and architecture mismatches.
- Organizational: Without a shared governance model between IT and OT, the two sides speak different languages and answer different incentives. You need internal digital diplomacy.
- Lifecycle mismatch: IT operates on a three-to-five-year refresh cycle. OT expects equipment to run for 20 years. When execution begins, those two timelines crash into each other.
- Architecture and legacy: Manufacturers quickly find that wireless has its limits, and replacing millions of dollars of decades-old legacy equipment isn't practical. Without a modular, componentized infrastructure, integrating new AI or analytics with legacy protocols can quickly become complicated and costly.
Q: Which stall points are most fixable, and which are structural?
A: The most fixable are use-case selection and workforce empowerment. Instead of building massive infrastructure first, make the most of the data infrastructure you already have by assessing it and identifying the gaps that stand in the way of seamless integration. Ask, "What can we fix today that brings immediate value?" Get the small wins, fast, frugal and flexible, that can build into big wins. We can also close the skills gap by using AI as a copilot, a coach and a teammate, not a be-all-end-all replacement. That lets workers build expertise using documented playbooks and faster simulation iterations.
The structural challenges are the gap between IT's five-year and OT's 20-year lifecycles, the vast amount of legacy brownfield assets in existing facilities, and the lack of unified governance. You can't overhaul infrastructure designed to operate for decades overnight. That takes continuous reinvention and long-term collaboration between hardware and connectivity vendors.
Q: How do IT and OT priorities collide, for instance security patching versus uptime?
A: It comes down to the difference between managing data and managing physical reality. IT is used to a three-to-five-year cycle where you can push an update, reboot a server or rely on redundancy without physical consequences. In OT, the system is designed to run for 20 years. With 49% of respondents citing enhanced safety as a top driver, systems must communicate reliably and securely. Adding typical IT redundancy or making frequent, uncoordinated changes often adds more hardware, more complexity and more points of failure on the line.
Also, in OT, context is constantly evolving on the plant floor, so you must monitor both model drift and actual value. If IT pushes a patch or changes network behavior without understanding the physical control loop, you break the deterministic nature of the line. That's why we need a new governance model and digital diplomacy. Both sides must stop viewing the network to move data and start seeing the backbone infrastructure as a competitive advantage that must remain reliable and resilient.
Q: The survey cites unplanned downtime (36%), security exposure (30%) and lost revenue (24%). Which concerns you most, and what does a disruption cost in a real operation?
A: Unplanned downtime and what I'd call "bad decision-making from bad data" concerns me most. In a real operation, these risks are all tied together: downtime directly causes lost revenue, and security exposure compromises safety. In today's environment of macro uncertainty and reshoring, you can't afford fragile operations, especially when disruptions translate directly into project delays and cost overruns.
In a real manufacturing or automotive operation, a disruption doesn't just cost thousands of dollars a minute in halted production. It breaks your hyper-resilience. If you're reshoring and setting up infrastructure fast, or running lean, an unplanned stop ripples through the entire supply chain. Worse, if your IT/OT integration has a flaw and feeds bad context into an automated system, that's garbage in, poison out. You're not just looking at a paused line. You're looking at scrapped batches, damaged equipment or safety incidents.
Q: Seven in 10 say performance optimization is the driver, and two-thirds point to analytics. What does that look like in practice?
A: First, it reinforces the importance of focusing on OT operations from the start, because they drive the bottom line. That naturally produces the other top motives: increased agility (57%) and cost reduction (56%). In practice, unlocking this means moving away from treating analytics as an isolated dashboard and turning it into "Physical AI," humans and machines working together on the plant floor. It shows up in a few ways:
- Surfacing the invisible: Humans and AI are both great at pattern recognition, but AI can connect data in ways we can't imagine surfacing micro-inefficiencies on the line that people can't see.
- Agentic AI for contextualization: Using agentic AI to automatically contextualize raw OT data at the edge or database level, so engineers aren't drowning in raw numbers.
- AI as coach and copilot: Using tools, like how we're structuring Belden AI, where AI acts as an assistant rather than the sole decision-maker, with transparency into how it reaches its recommendations. This helps engineers experiment and run simulations faster, generate 30% to 50% of routine code and configurations, and use documented playbooks to set up or tweak infrastructure rapidly.
- Living infrastructure: Measuring traffic and performance in real time so the infrastructure itself stays reliable, modular and responsive, directly supports a specific business need and can scale as operations grow.
About the Author
 Len Vermillion


 Leaders Logo
Leaders relevant to this article: